Turn AI from a Blank Check into a Managed Budget
Every project gets a token budget, and smart routing in an AI-specific gateway matches each request to the cheapest model that can do the work
Request a Demo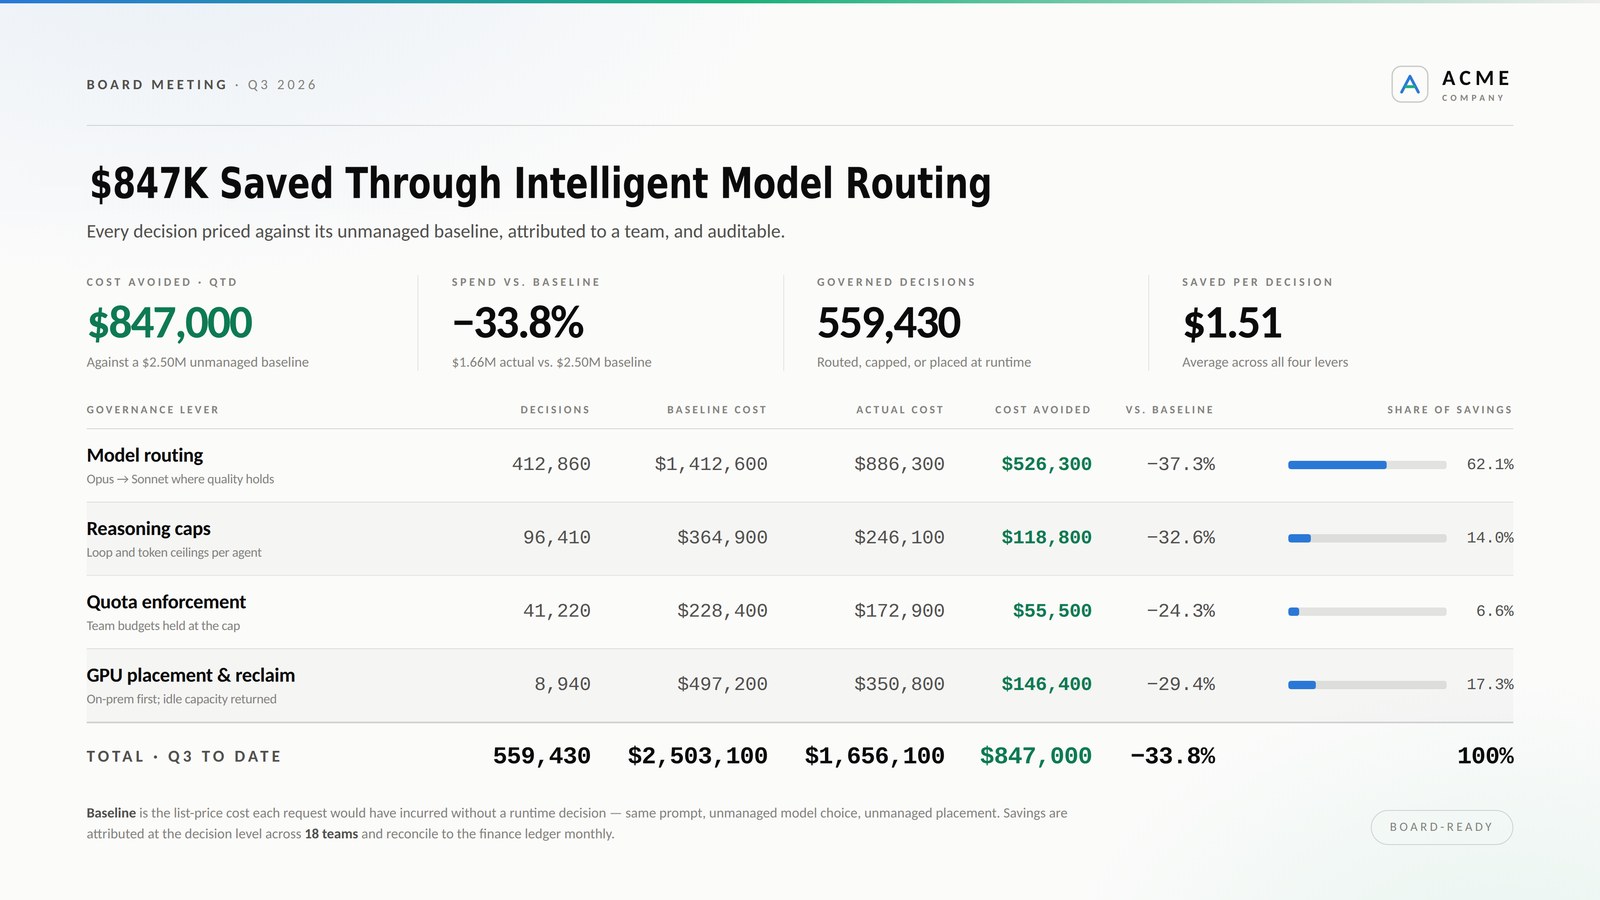
Manage to FinOps Budgets Without Slowing AI Work
Budgeted
Token budgets are set once per user, project, or tenant, then applied as requests run rather than reconciled at the end of the month
Routed
The LLM Gateway matches each request to the model its complexity and latency require, so frontier models handle only what earns their price
Measured
Usage, latency, and throughput are tracked by team, project, and model, so you see what a cheaper model costs in speed before standardizing on it
Not Every Prompt Deserves Your Most Expensive Model
Klique’s LLM gateway routes routine work to lower-cost or self-hosted options and reserves premium models for what actually needs them. AI services become routable resources alongside your GPU hardware, with smart routing, budget enforcement, and billing built in
Frontier by Default
- Frontier models used for routine work not worth the premium
- Token spend reconciled monthly and manually traced back to teams
- Budgets that live in a spreadsheet, not actively managed
Frontier by Exception
- Each request routed to the model its work actually requires
- Budgets applied while the request runs, per user, project, or tenant
- Ceilings that live in the gateway, on the path of every call